
Forecast what happens next, and how sure you are
Forecaster puts 25+ time-series algorithms under one governed surface. Scheduled runs keep forecasts current, side-by-side backtests decide which model earns the job, and every prediction ships with the confidence range that tells you how much weight it can carry.
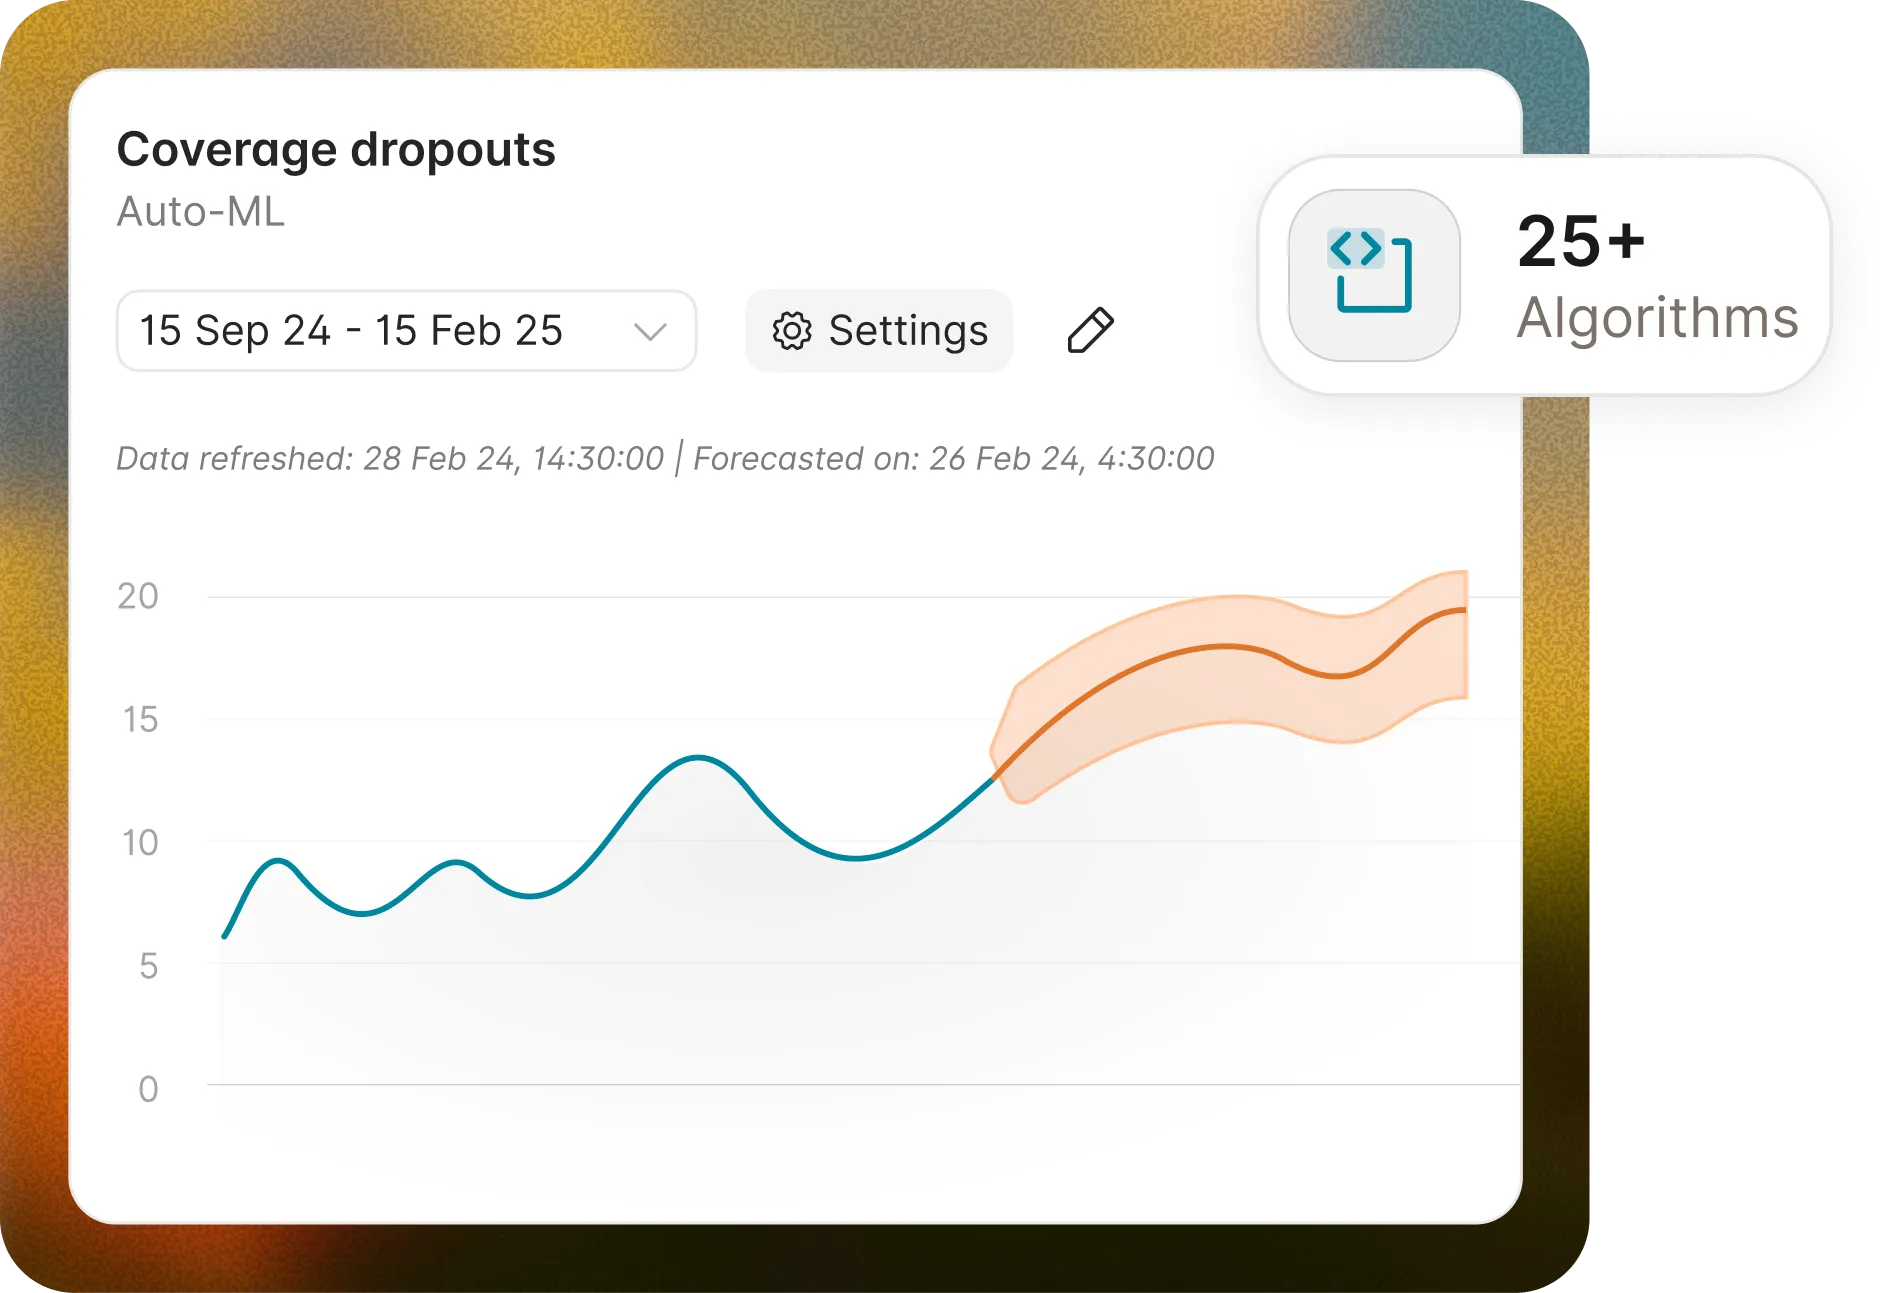
Empowering Businesses with Predictive Insights | Forecaster
A walkthrough of Forecaster, DataByte’s enterprise time-series forecasting agent with automated preparation, 25+ algorithms, AutoML, and scheduling.
Twenty-five algorithms, and a comparison you can defend
Different series want different models. A daily operational metric with a hard weekly rhythm is not the same problem as a twelve-month financial trend, and picking one algorithm for both is how forecasts quietly go wrong.
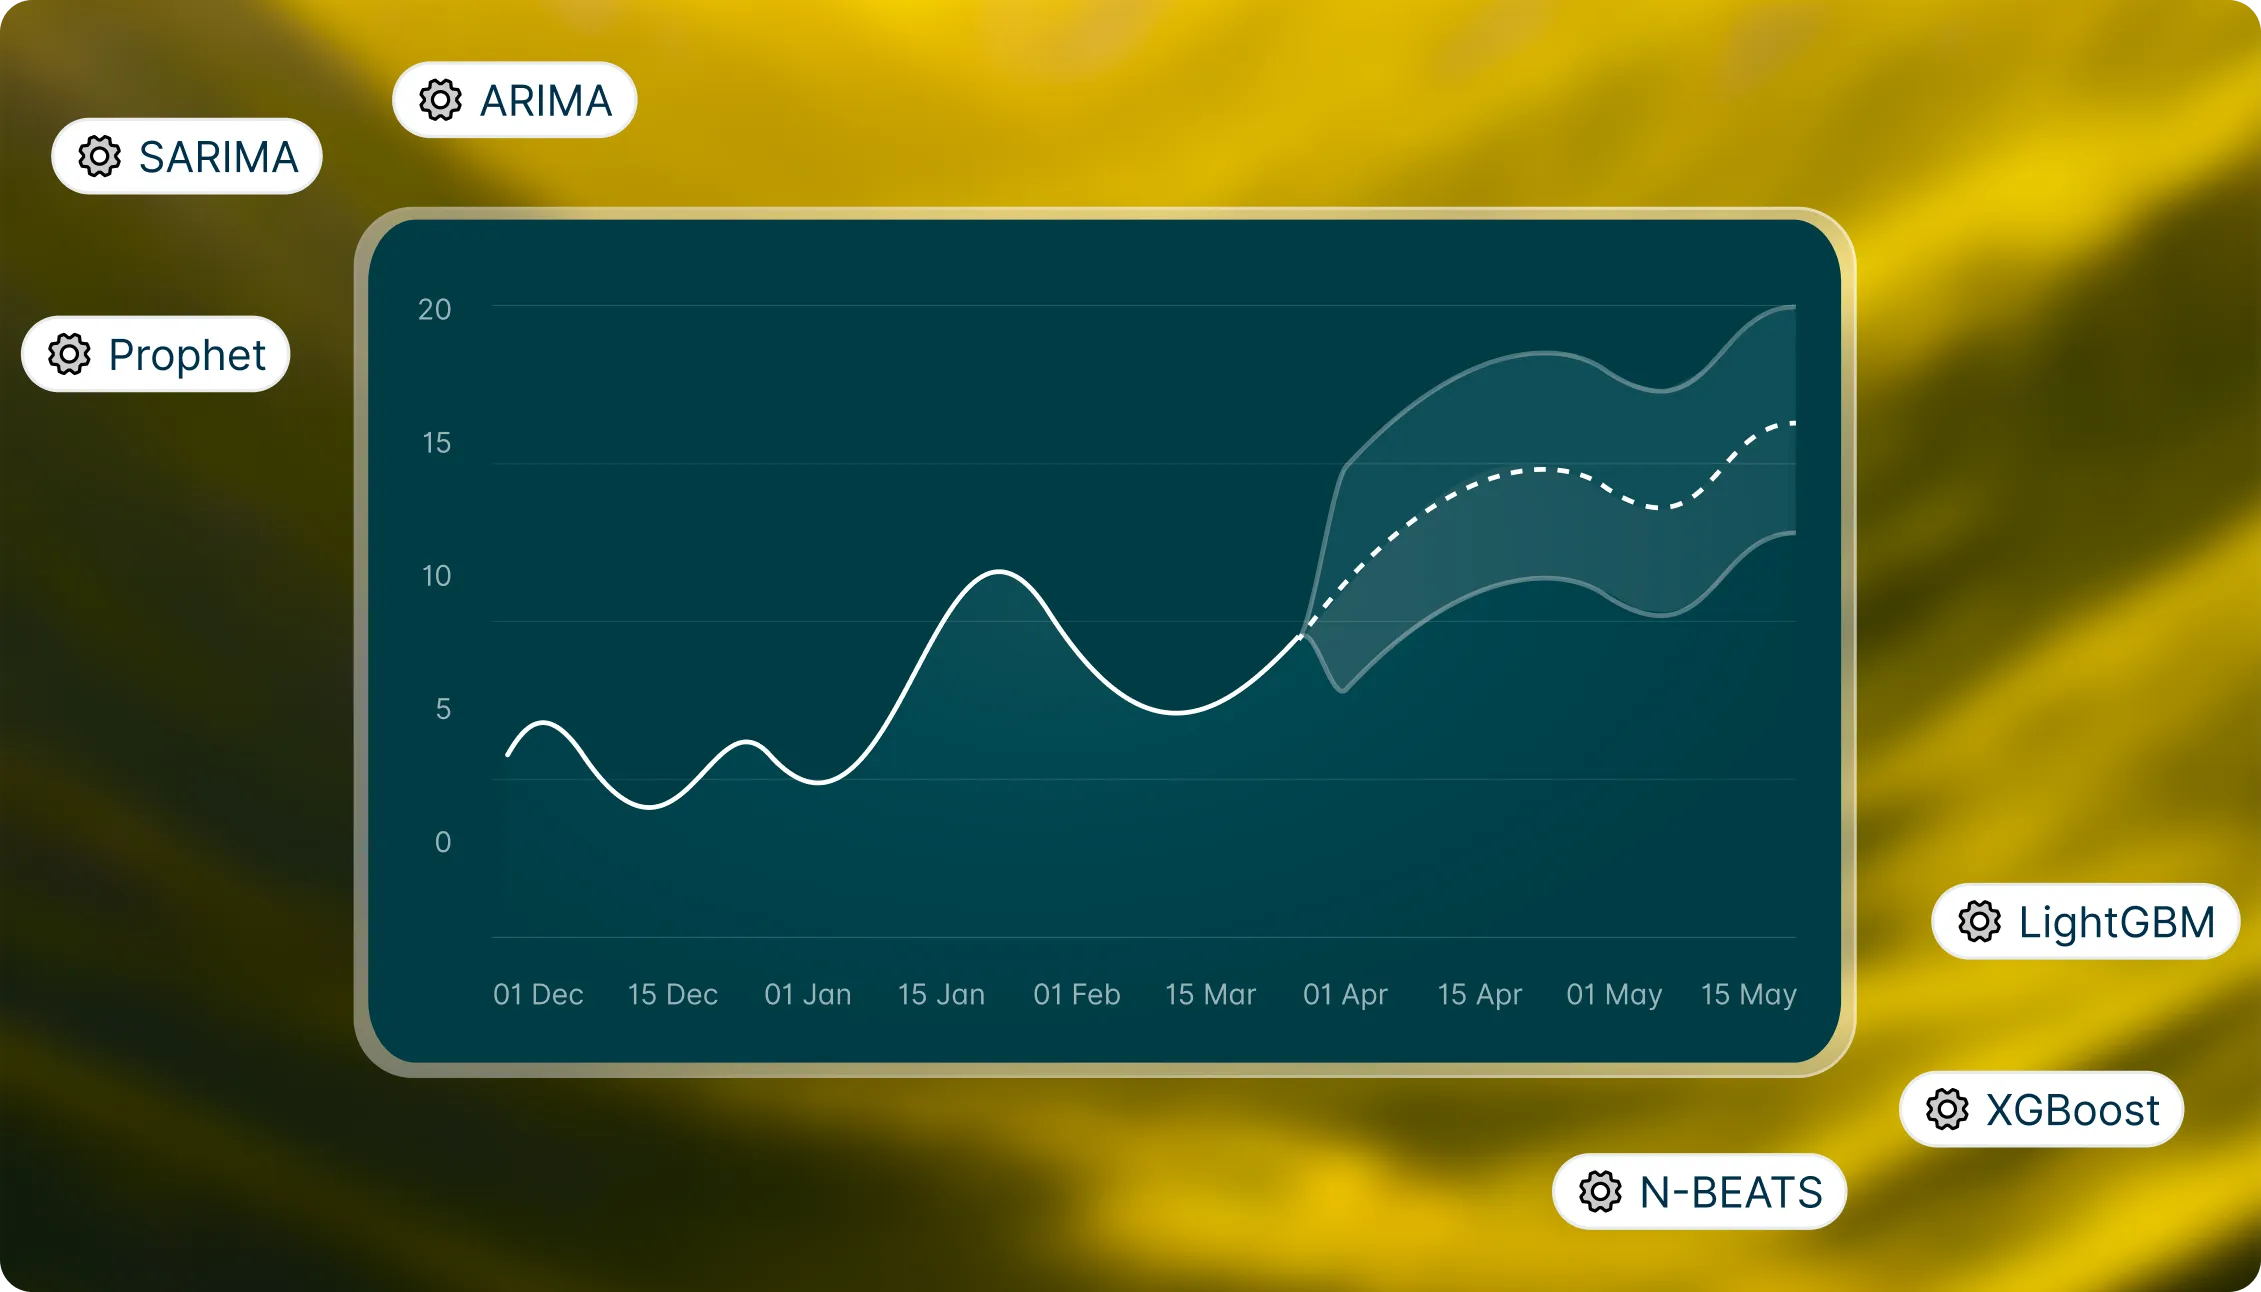
Forecaster ships more than twenty-five time-series algorithms in a single library: classical statistical models such as ARIMA and its seasonal extension SARIMA, gradient-boosted learners such as LightGBM and XGBoost, Prophet, and deep-learning approaches such as N-BEATS.
Rather than settle the argument in a meeting, settle it with a backtest. Forecaster runs candidate models against the same history and reports the results side by side, so the choice is made on evidence.
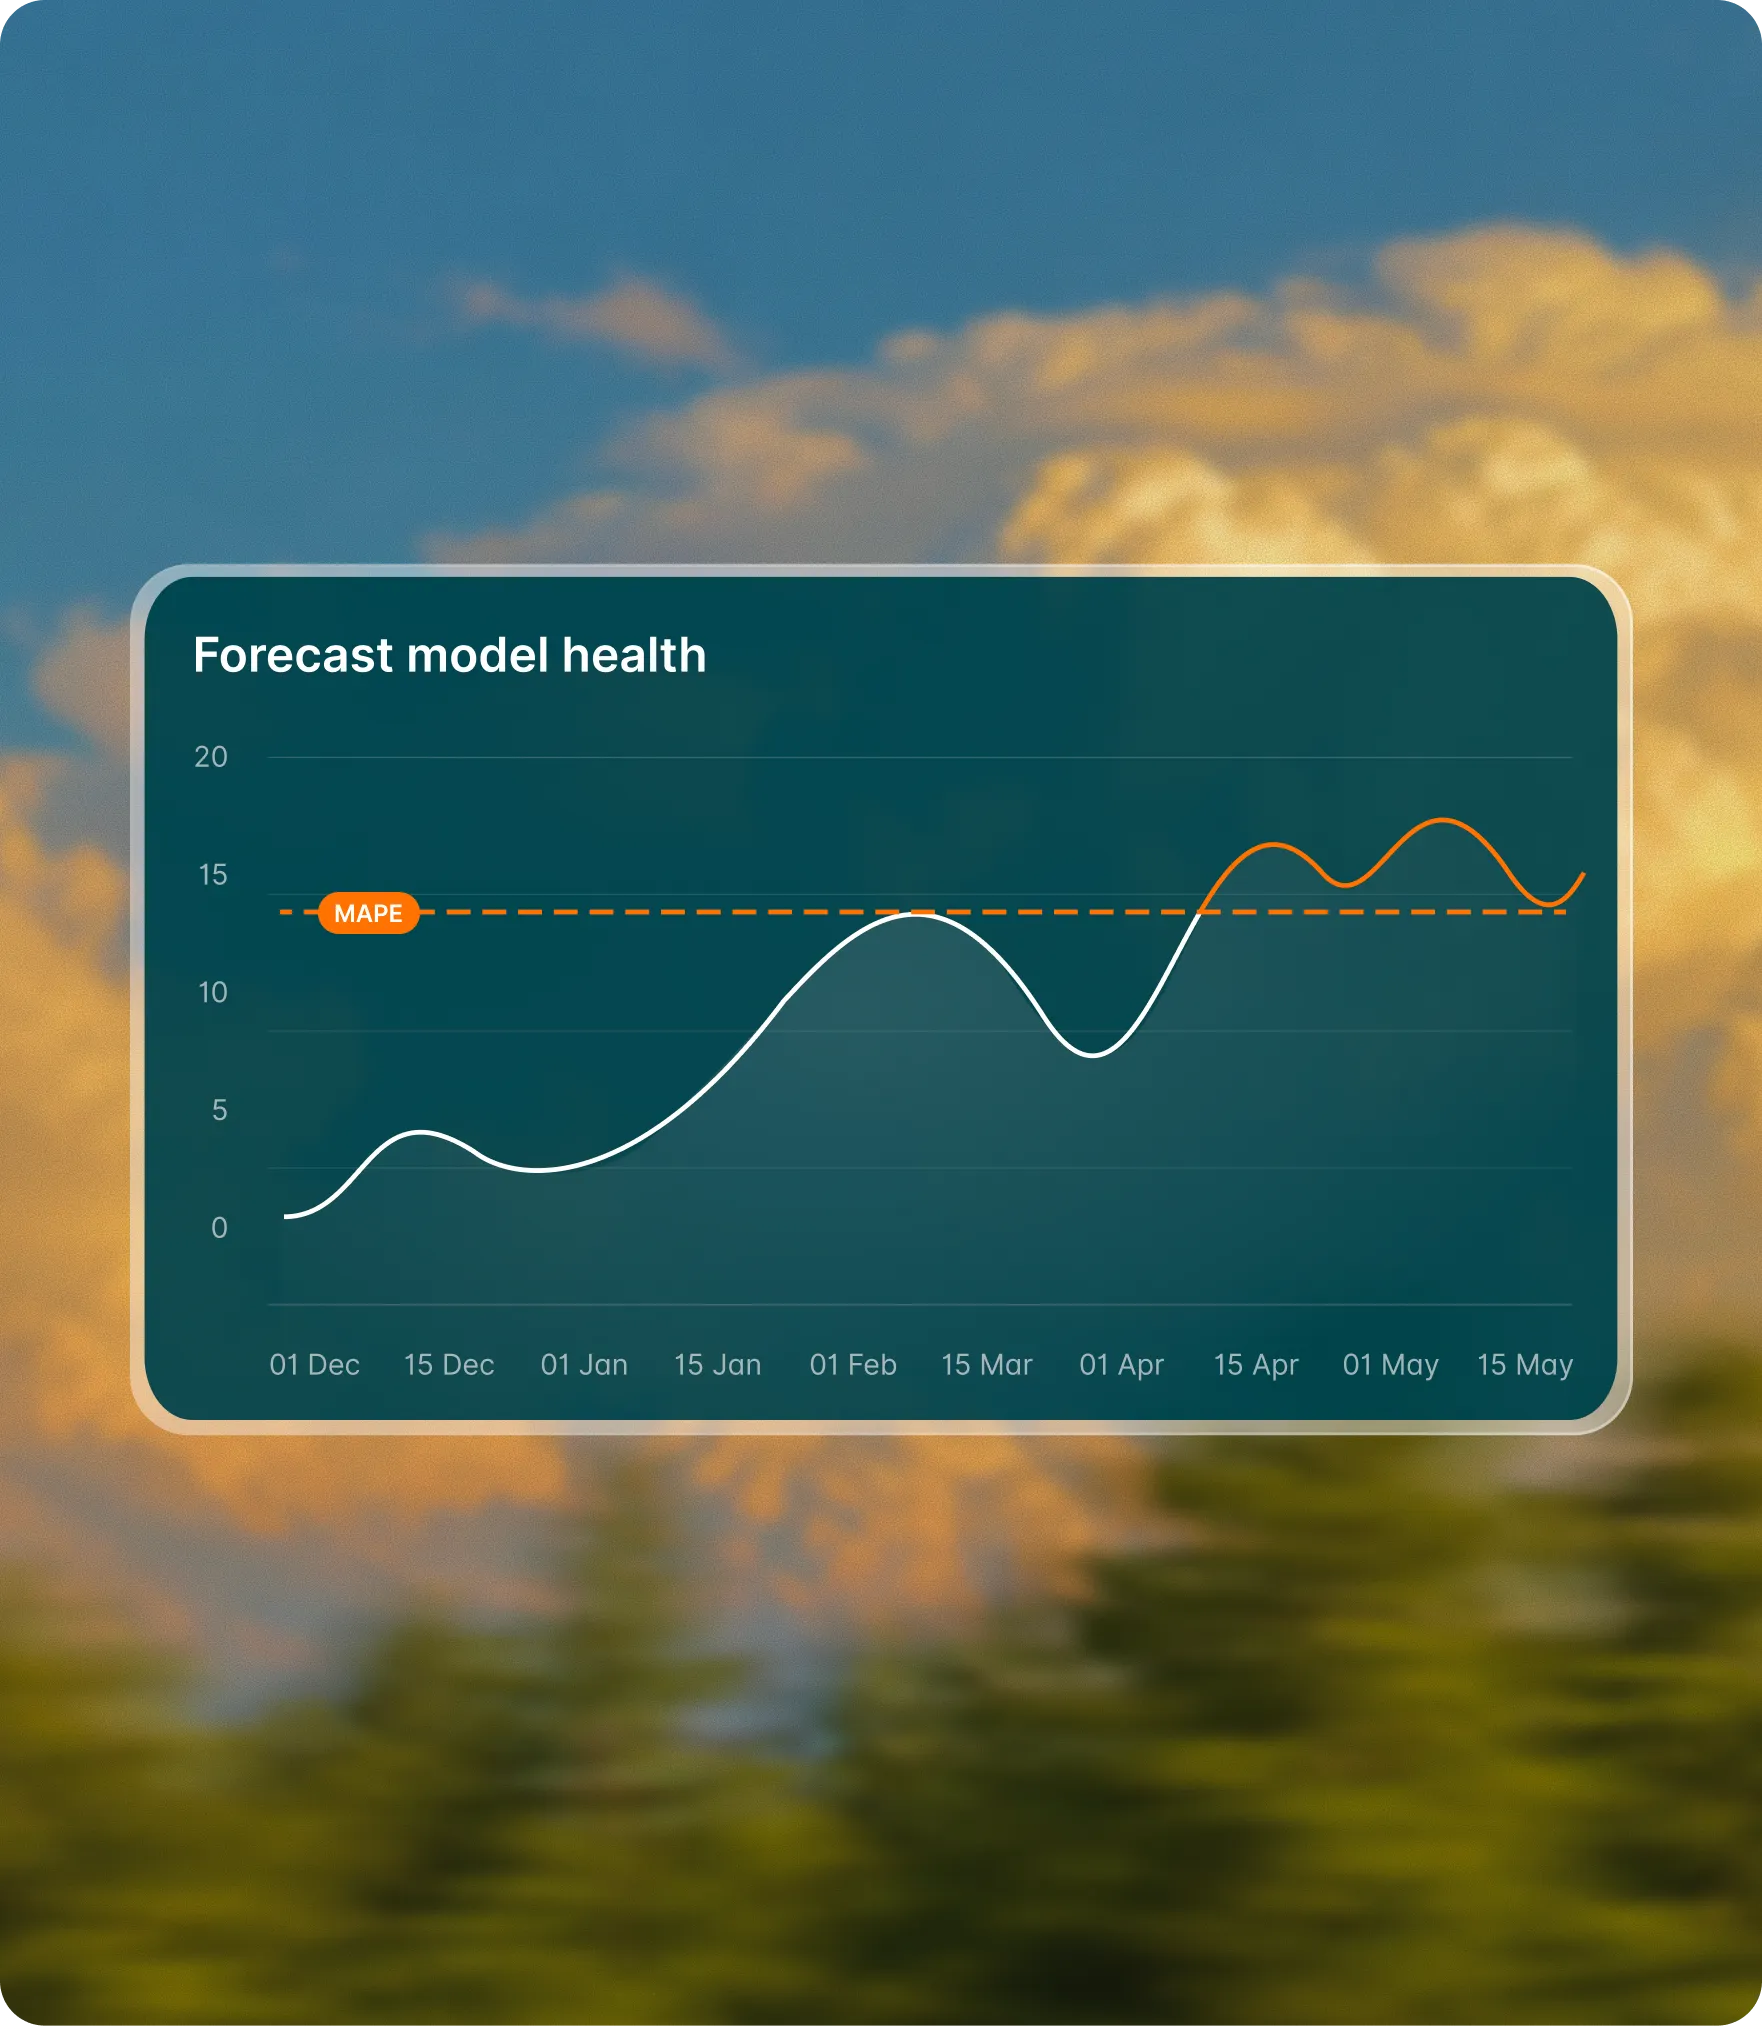
Accuracy dashboards then keep reporting MAE, the typical error in the units you actually care about, and MAPE, the average percentage miss. Scheduled runs keep the winning model producing on a cadence. Nobody has to remember to refresh a spreadsheet.
Most forecasting failures are data failures in disguise
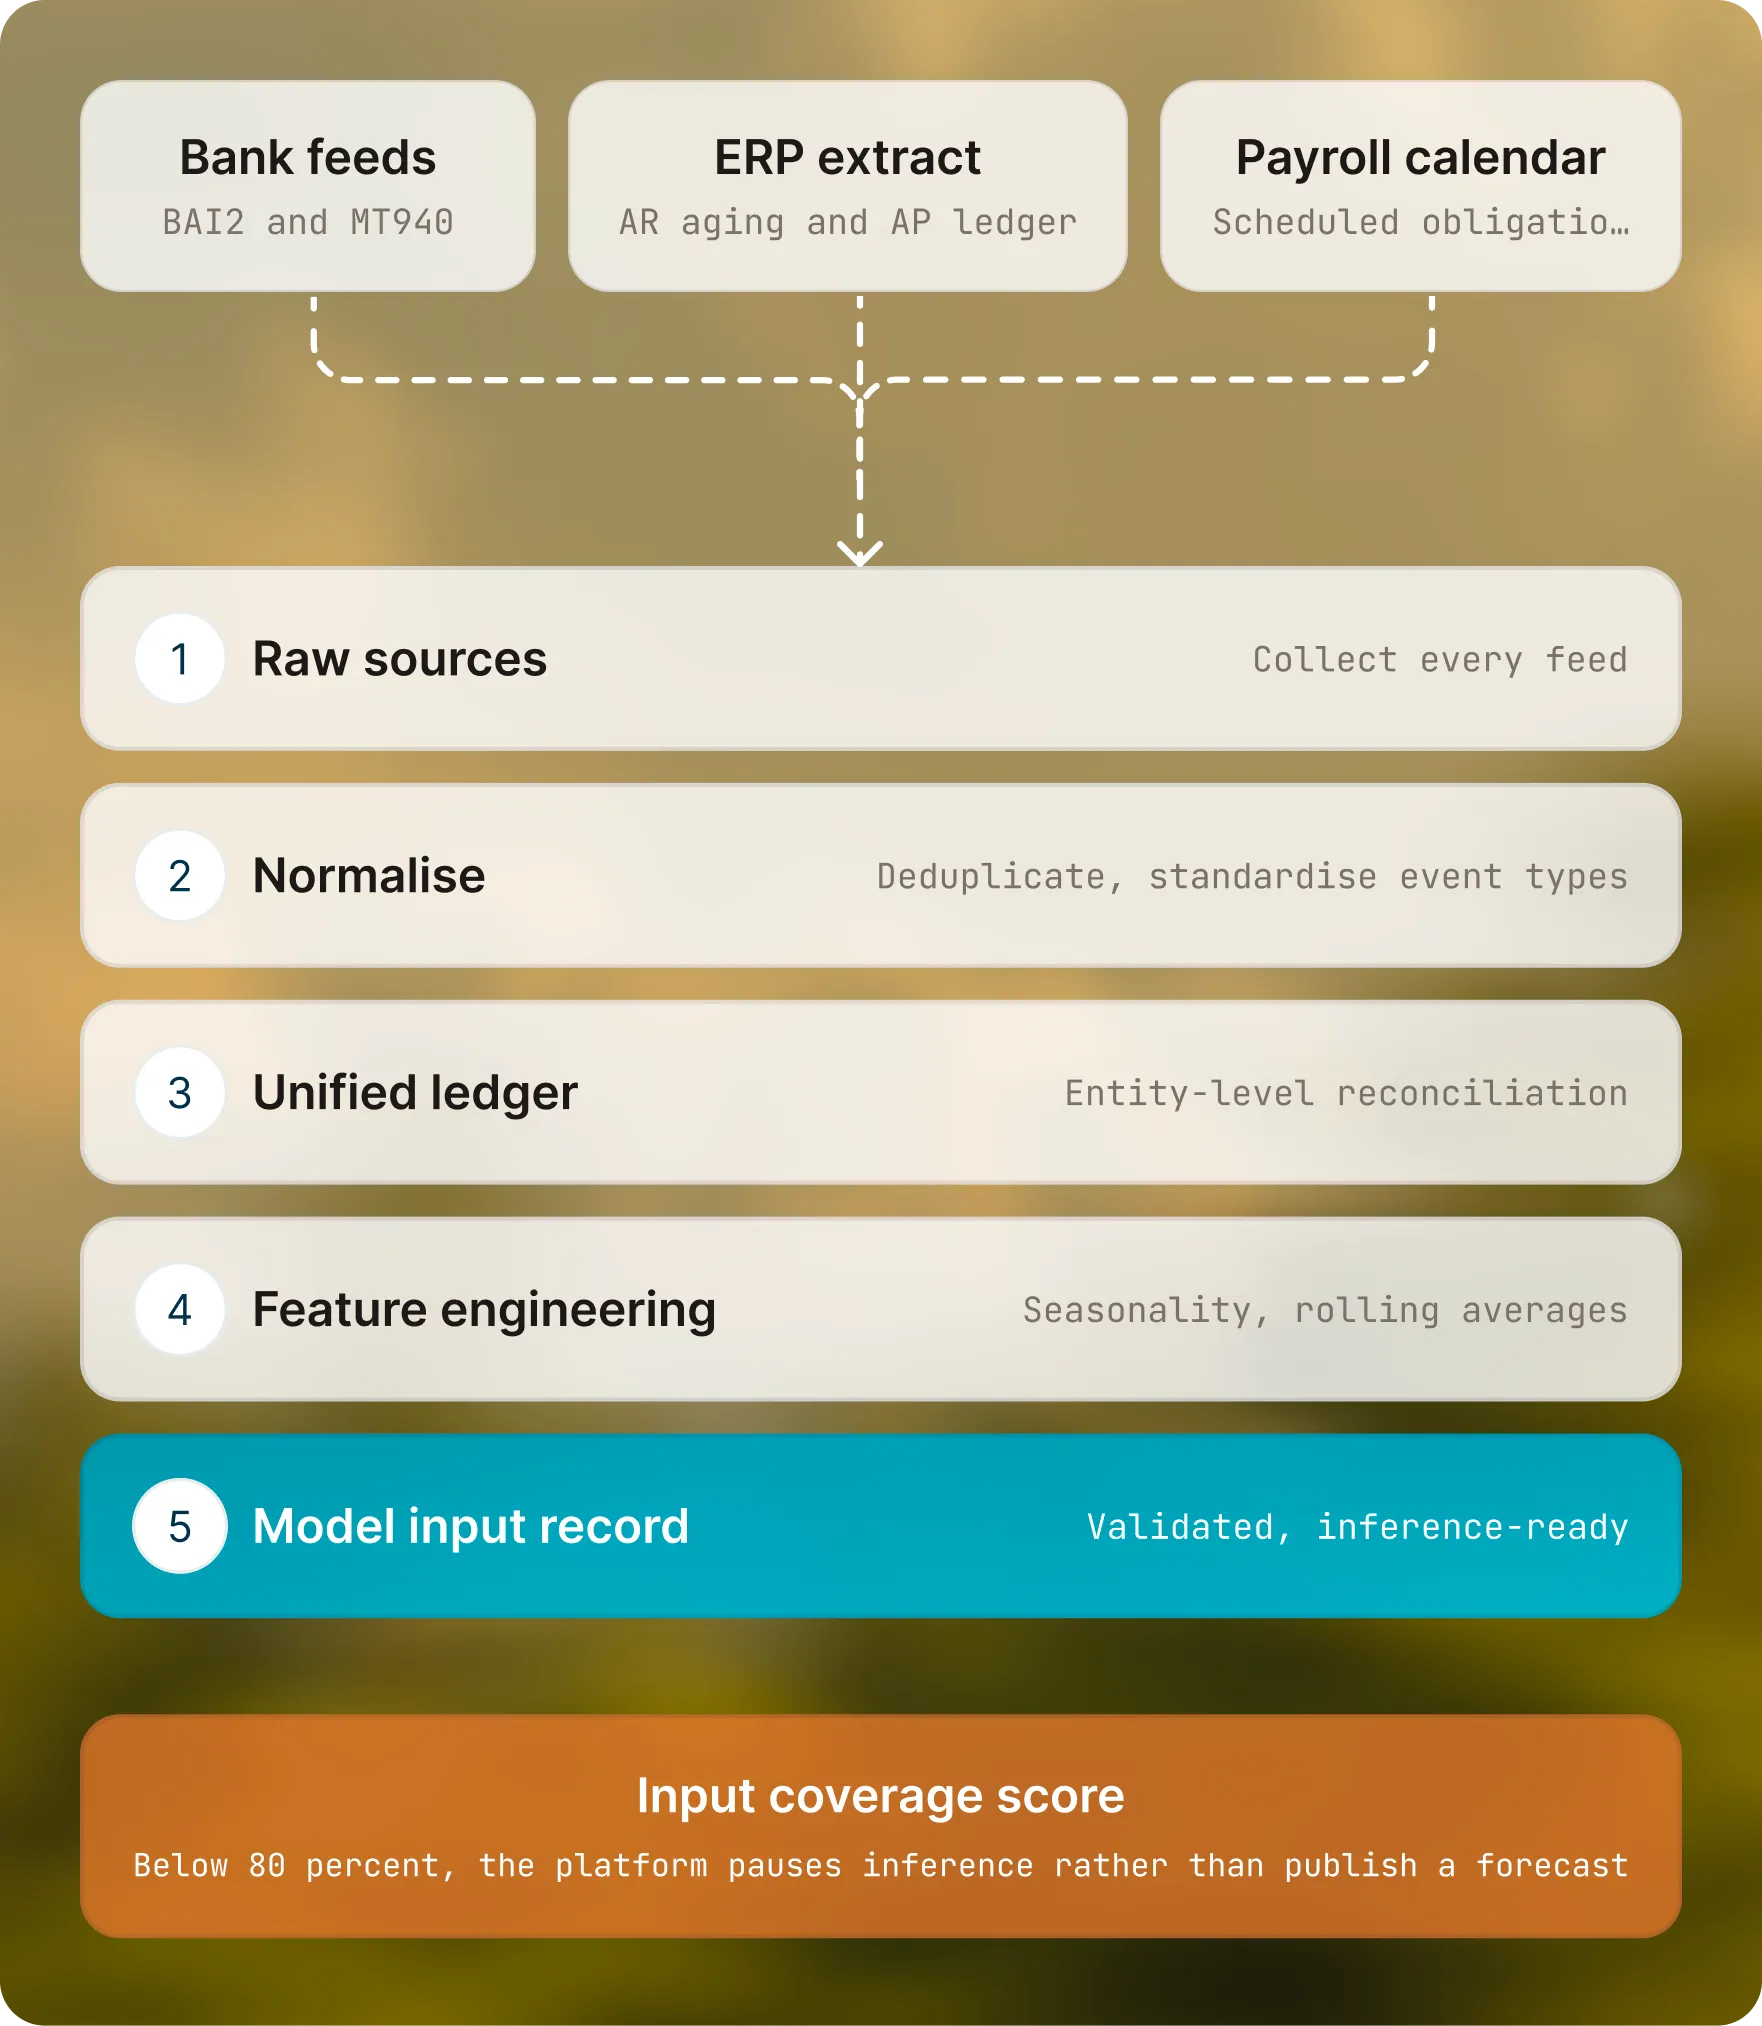
Cash Forecaster, the treasury configuration of the module, makes the point concretely. It draws on three live feeds: bank statements in BAI2 and MT940 format, ERP extracts covering receivables and payables, and the payroll calendar.
Each arrives in its own shape, on its own schedule, with its own idea of what counts as an event. A model handed that directly will produce a number, and the number will be worthless.
So five stages sit between the feeds and the model. They are raw collection, normalisation that deduplicates records and standardises event types, entity-level reconciliation into a unified ledger, feature engineering that derives signals like seasonality indicators and rolling averages, and a final completeness check before anything reaches inference.
An input coverage score aggregates how much of that arrived intact, across bank statement coverage, ledger completeness, payroll coverage, feature derivation, and historical backfill depth.
Drop below eighty percent and the platform pauses rather than publish. It would rather show you nothing than show you something wrong.
What happens if the money arrives ten days late
Every planning conversation eventually turns into a what-if. What if our largest customer stretches payment? What if revenue softens?
What if we accelerate payments to protect a critical supplier? Those questions are usually answered with instinct and rough arithmetic, which is fine right up until the answer matters.
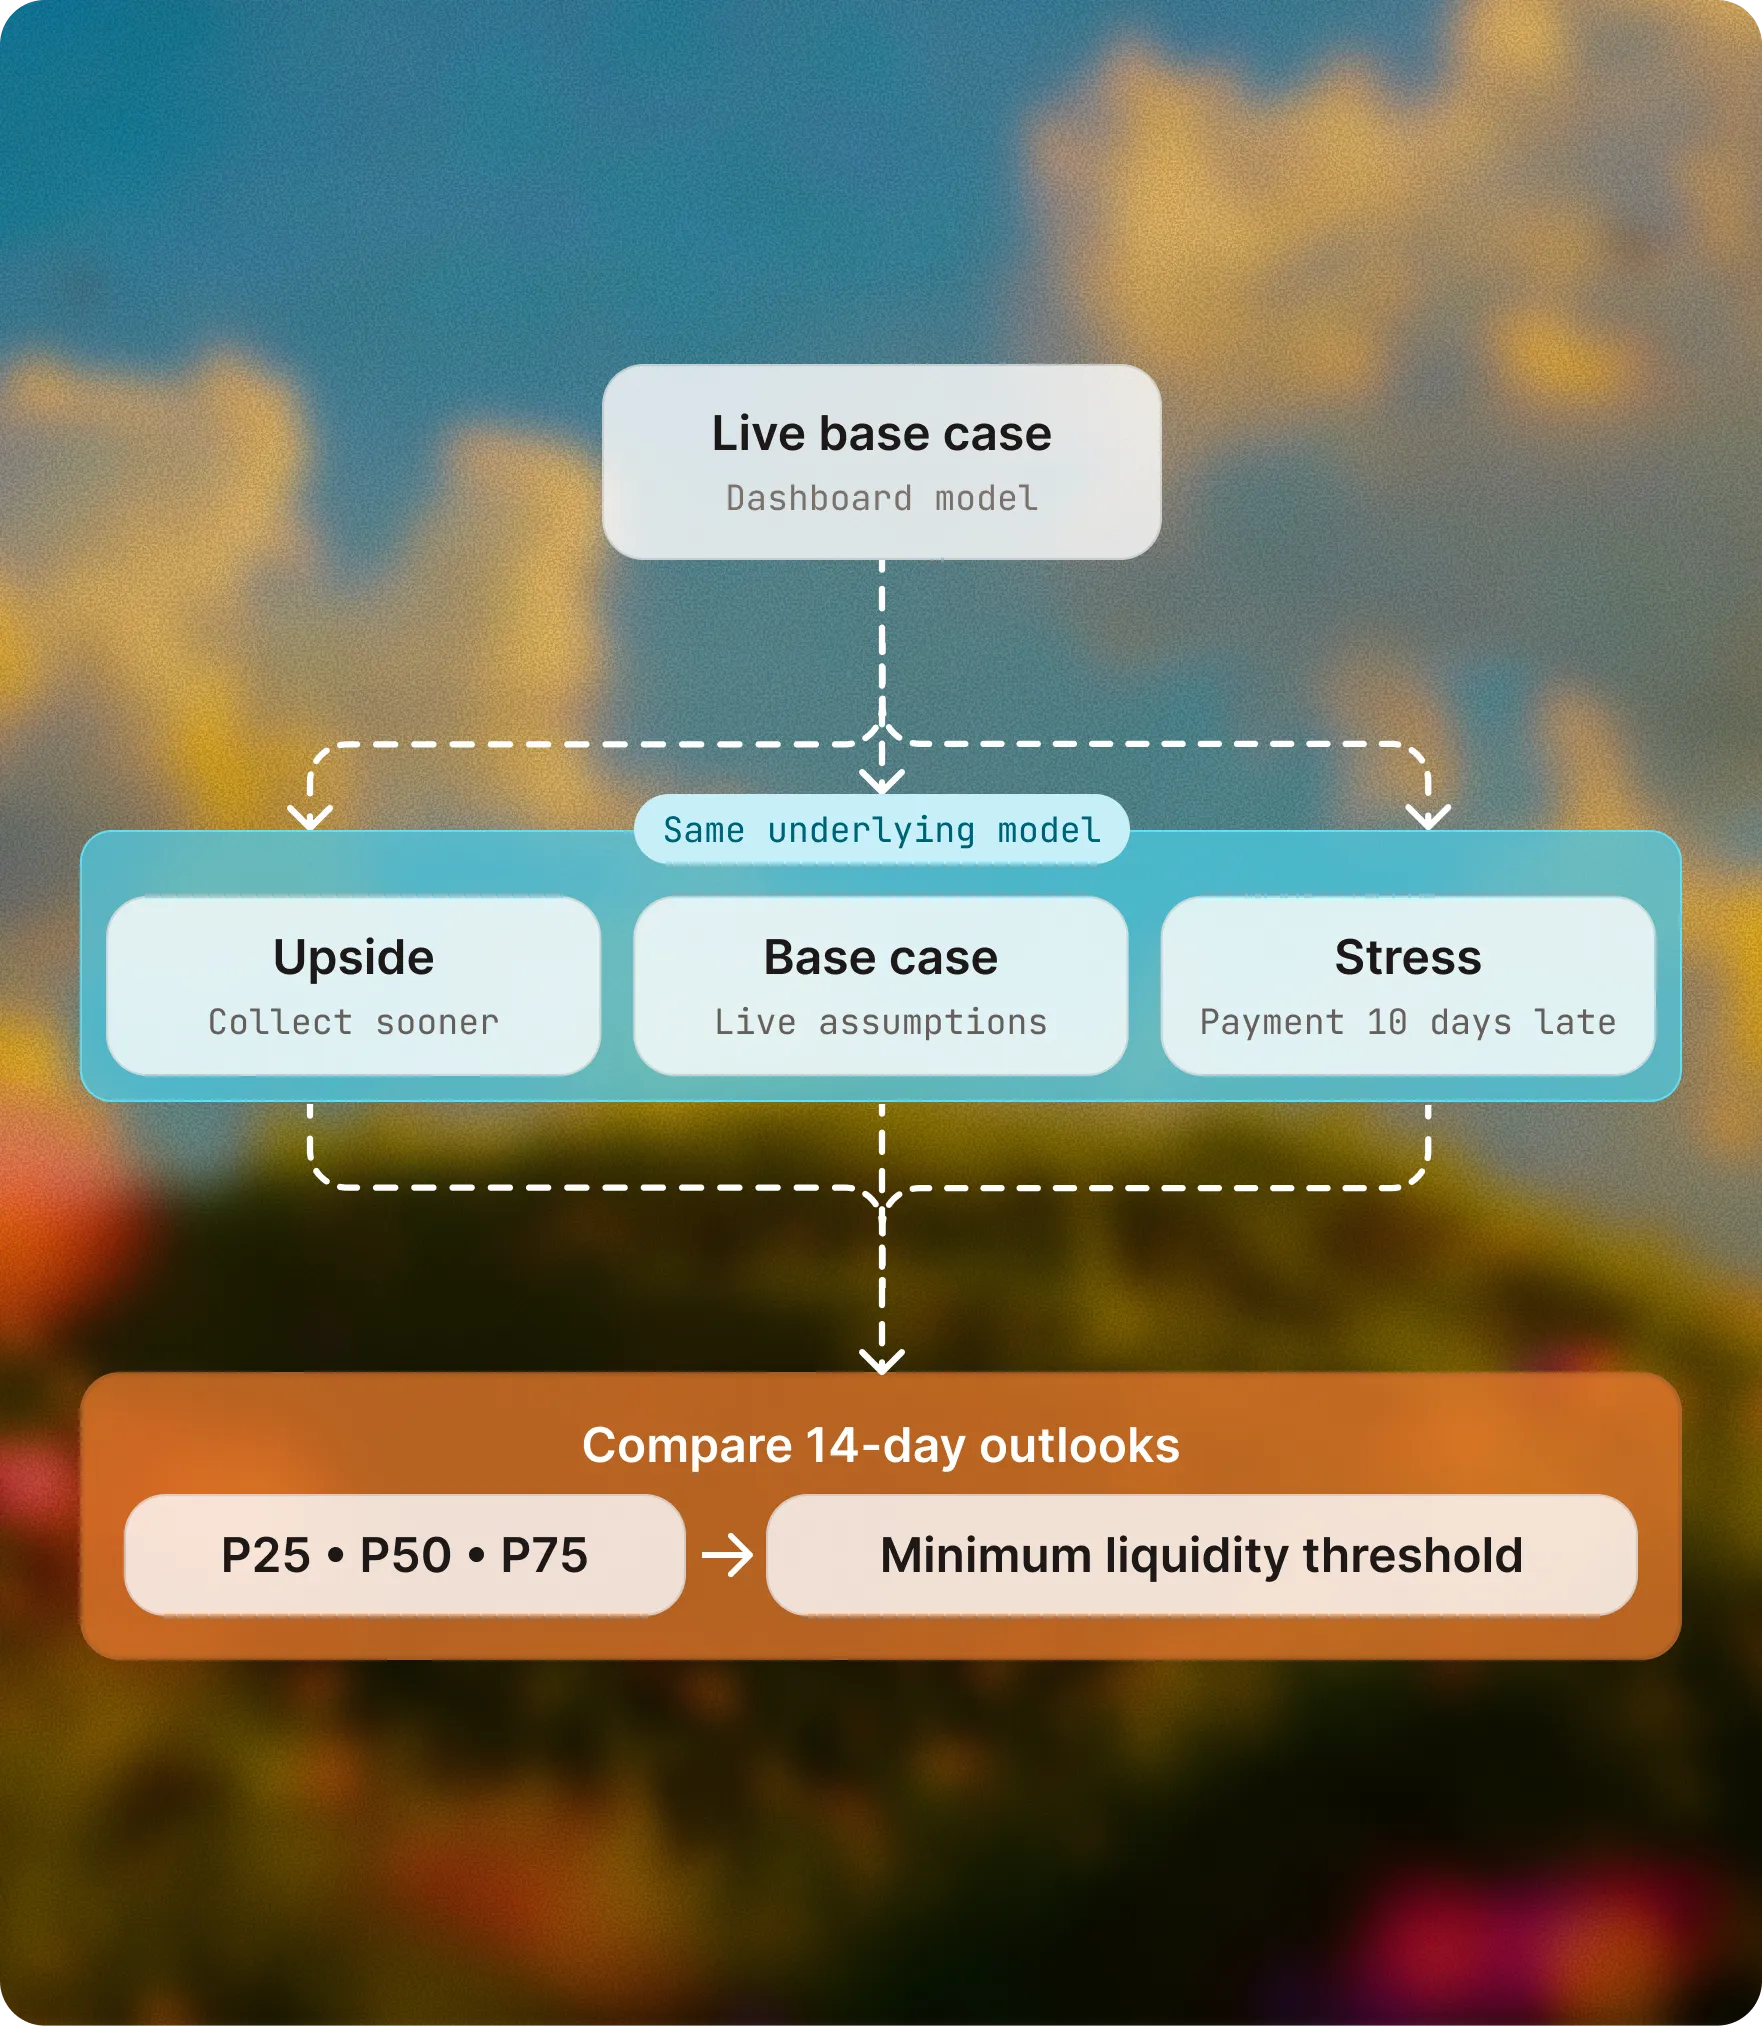
The scenario module turns them into structured analysis. You start from the live base case, the same model driving the main dashboard, then adjust bounded parameters: DSO extension, collection acceleration, AP payment stretch, and revenue growth.
Stress, base case, and upside run on the same underlying model, so a stress test is a real projection rather than a hypothetical drawn on a whiteboard.
Results overlay as P25, P50, and P75 on the fourteen-day chart, with a summary table that compares all three at once and shows each against your minimum liquidity threshold.
A forecast that tells you when it is starting to be wrong
Models decay. They learn historical patterns, and when the business moves, those patterns stop holding. The damage is rarely dramatic; the forecast simply drifts, quietly, for weeks. Forecaster treats that as a monitoring problem rather than an act of faith.
Every horizon carries its own model card showing the algorithm in use, current MAPE against its threshold, an eight-week accuracy trend, the last retrain date, and the training data range.
Two drift signals run underneath. Population Stability Index watches whether the distribution of an input feature has shifted since training, and forecast error drift watches whether predictions are becoming systematically biased in one direction, the failure mode an acceptable average error will happily hide.
SHAP values rank feature importance at each horizon, so the model can explain which variables are driving it. When a MAPE threshold is breached, retraining triggers automatically, with optional AutoML tuning on the run.
The confidence score on the dashboard composes all of it: historical accuracy at forty percent, horizon decay at twenty-five, data freshness at twenty, and forecast stability at fifteen.
Forecasting rarely stands on its own.
A forecast is the end of a chain that starts at ingestion and ends at a governed report. These are the pieces on either side of it.
Put a number, and a range, on next quarter.
See Forecaster backtest candidate models on your own history, schedule the winner, and report accuracy as it runs.